Building an Offline Work History Vector Store: Querying Career Notes with ChromaDB
Ads
When preparing multiple job applications, you often re-read old performance reviews, project logs, commit histories, and client emails to find relevant examples. Pasting these documents into a public chat box is tedious and exposes proprietary company data to third parties.
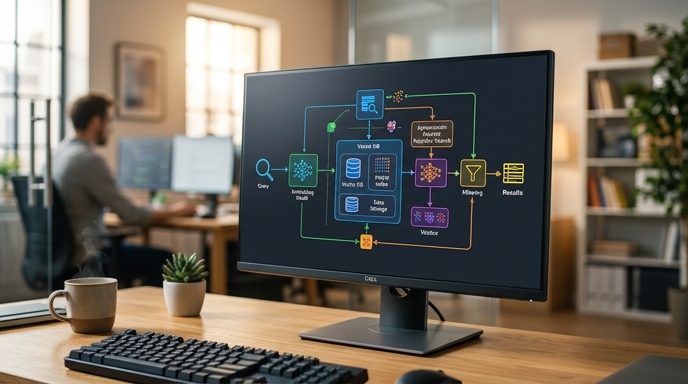
A Retrieval-Augmented Generation (RAG) system solves this locally. By storing your career notes in an offline ChromaDB vector store, you can query years of project documentation in plain English and pass only the relevant context into your drafting prompts.
Why Career Context Needs a Vector Database
Pasting dozens of pages of past work history into a standard prompt degrades model focus. Models can blend details from different jobs or invent metrics to link unrelated notes.
A local vector database indexes your career notes as mathematical embeddings. When you ask, "What metrics do I have on optimizing SQL queries?" the database retrieves the exact paragraphs from your past project notes, grounding the language model in your actual achievements.
Building the Local Vector Store with Python
You can build this local system using Python libraries that run on your machine. Install the dependencies with pip install chromadb sentence-transformers.
Create an ingestion script named index_career.py:
import chromadb

# Initialize local persistent client
client = chromadb.PersistentClient(path='./career_db')
collection = client.get_or_create_collection(name='career_history')

# Sample career entries from your notes
career_notes = [
    'Led migration of 4 microservices from AWS to bare-metal in Q3 2023, reducing monthly infrastructure costs by $14,000.',
    'Designed an automated onboarding checklist in Python that cut developer provisioning time from 3 days to 4 hours.',
    'Resolved critical PostgreSQL replication lag issues under high write loads during Black Friday sales.'
]

# Index documents with unique identifiers
collection.add(
    documents=career_notes,
    ids=['note_001', 'note_002', 'note_003']
)
print('Career history successfully indexed.')
This script saves your career history into a persistent local directory that requires no network connections.
Querying Your Work History for Application Answers
When drafting an interview answer or tailoring a resume bullet, query your collection using a search script to find the most relevant snippets from your notes:
results = collection.query(
    query_texts=['database performance and cost reduction'],
    n_results=2
)
print(results['documents'])
Pipe those retrieved snippets directly into your prompt: 'Draft a behavioral interview answer explaining how I reduced infrastructure costs using ONLY the retrieved facts below. Do not invent any additional systems or figures.'
Frequently Asked Questions
Does running ChromaDB locally send any data to external servers?
No. When initialized with PersistentClient, ChromaDB runs entirely as an embedded database within your local Python environment, storing all vectors on your drive.
What embedding model does ChromaDB use by default?
ChromaDB uses all-MiniLM-L6-v2 by default. It downloads locally on first run and executes on standard CPUs without requiring a dedicated GPU.
What document types can I index in this vector store?
You can index text extracted from markdown files, performance reviews, job descriptions, project tickets, or personal notes. Convert documents to plain text strings before indexing.